Correlation Difference Ratio
The Correlation Difference Ratio compares the correlation structure preservation between one half of the original dataset and its avatarized version against the correlation structure between the two halves of the original dataset. For interpretability, it uses the natural variability of the data as a reference.
For both comparisons, it computes the mean absolute difference in correlation coefficients across all pairs of numerical variables.
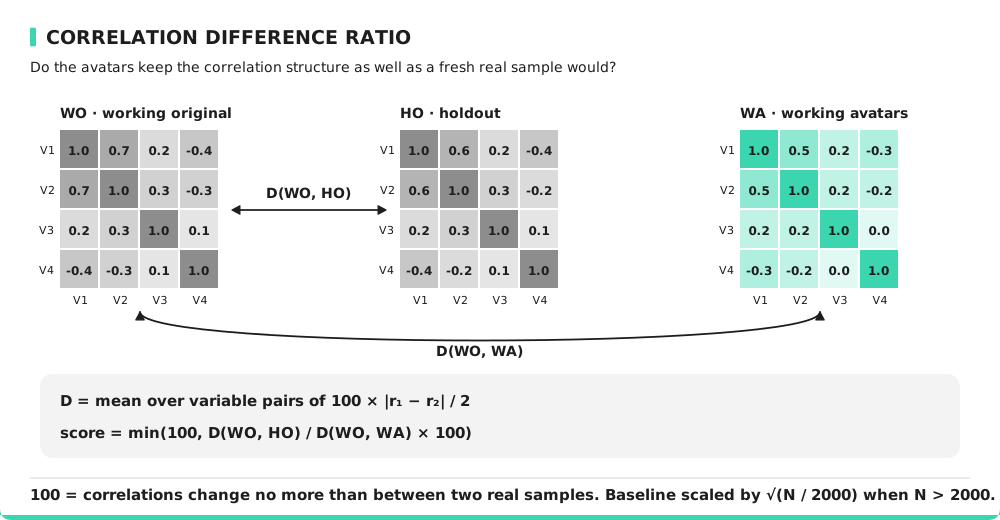
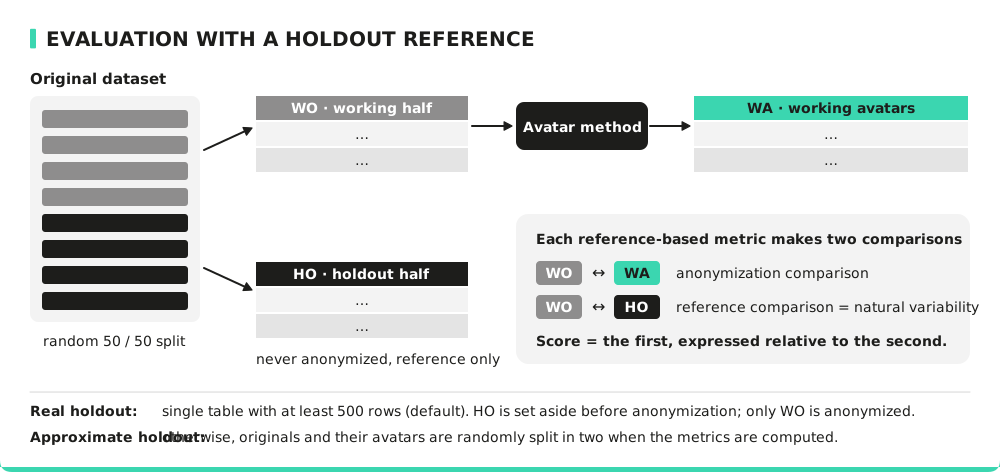
This is a reference-based metric: it compares the anonymization (WO vs its avatars WA) against the natural variability of the real data (WO vs a held-out reference HO).
- WO — working half original: the part of the original data that is anonymized.
- WA — working avatars: the avatars generated from WO.
- HO — holdout half original: a second, untouched sample of real records, used only as a reference.
On datasets large enough (by default ≥ 500 rows) a real holdout is set aside before anonymization; on smaller ones an approximate holdout is drawn by randomly splitting the data when the metrics are computed. See the "Evaluation with a holdout reference" section in the Technical Assessment report.
Comparison Strategy (Holdout)
To compute the final score returned to the user, we perform the following steps:
- Obtain the working half WO and a disjoint holdout half HO from the real data (a real or approximate holdout — see the note above).
- Take the working avatars WA, generated from WO.
- Compute the mean absolute difference in correlation coefficients between WO and WA (avatar difference).
- Compute the mean absolute difference in correlation coefficients between WO and HO (reference difference).
- Compute the ratio:
reference_difference / avatar_difference × 100, capped at 100.
Interpreting the Correlation Difference Ratio
The result estimates the percentage of the reference correlation preservation obtained through avatarization:
- The closer to 100, the more avatars preserve the natural correlation structure of the dataset.
- Values close to 100 indicate that avatar correlations differ from original correlations as much as the two halves of original data differ from each other — good correlation retention.
- Values below 100 indicate that avatar correlations diverge more from original correlations than the natural variability would suggest — correlation structure degradation.
Metric Specificity
Advantages:
- Uses the dataset's own natural variability as a reference, making the result more interpretable than a raw difference.
- Provides a bounded score between 0 and 100.
- Intuitive percentage-based interpretation.
Limitations:
- Only applies to numerical variables using Pearson correlation.
- Sensitive to small correlation values (e.g., a change from 0.05 to 0.15 results in a large percentage difference).
- Does not account for non-linear relationships.
- Can be impacted by sample size variations between datasets.
- More likely to fluctuate on small datasets (fewer than 200 rows), where sampling variance can make the score less stable and harder to interpret.
Formula
For two Pearson correlation matrices and over numeric variables, the mean difference over pairs of variables, in percent:
With the number of rows of , the reference is scaled up on large datasets, where the difference between two real samples shrinks:
The score is 100 when .
How to Improve This Metric?
To improve the Correlation Difference Ratio score, you can adjust parameter k to help align correlations more accurately. You can also apply weighted projections by assigning higher importance to critical variables during data generation. Finally, you can use targeted data processing by applying transformations based on variable characteristics. Please consider using alternative metrics (e.g., mutual information) if the data contains non-linear relationships or categorical variables.